In a nutshell
Picture a car factory. Nobody hand-builds each car on the showroom floor — bolting on doors from memory and hoping the next one comes out the same. There is a production line: the design is captured as blueprints, a stamping press turns sheet metal into identical panels, robots weld to spec, and a quality station rejects anything out of tolerance — and the line keeps running, re-checking and re-stamping, long after the first car rolls off. Platform automation is that factory for your landing zones. You don’t hand-place management groups, policies, hub networks and subscriptions in the portal and pray they stay put; you write the design as code, and a pipeline stamps it out and continuously reconciles it so the live tenant always matches the blueprint. Change the blueprint (a pull request) and the line re-stamps; tamper with a finished part (a portal click) and the quality station catches the drift.
Everything in the previous seven Landing Zone design areas described a desired state — the management-group tree, the guardrail policies, the hub topology, the identity model. This design area is the machinery that makes that desired state real, repeatable, reviewable, and self-healing. Concretely it answers four questions: what language expresses the platform (Bicep or Terraform)? What accelerator bootstraps it from a known-good Microsoft baseline? How does an app team get a governed subscription on demand (subscription vending)? And what pipeline, identity and operating model deploy changes safely, forever? Get this wrong and your landing zone is a beautiful diagram that was true for exactly one day. Get it right and every change to the platform — a new policy, a new spoke, a new subscription — becomes a reviewed, tested, audited pull request.
This is the capstone of the series and unapologetically an advanced lesson: it assumes you already know what a management group, an Azure Policy assignment, a hub-and-spoke network and a subscription are, and now want to operate all of them as code at enterprise scale. If any of those are fuzzy, the earlier design-area lessons are the place to start.
Level: Advanced · Time: ~49 min
Prerequisites
- The earlier Azure Landing Zone design areas — especially Resource Organization (management-group hierarchy, subscriptions), Governance (Azure Policy, initiatives,
DeployIfNotExistseffects), Network Topology (hub-and-spoke vs Virtual WAN) and Identity (Microsoft Entra, managed identities, RBAC). - Comfort with at least one IaC tool — Bicep or Terraform — and the idea of a deployment being declarative and idempotent.
- Familiarity with git and pull-request workflows, and with a CI system (GitHub Actions or Azure DevOps Pipelines).
- The distinction between the Azure control plane (ARM: create/govern resources) and data plane (use them).
After this lesson you’ll be able to
- Choose a primary platform IaC language (Bicep vs Terraform) on the right criteria and defend the decision.
- Explain the current ALZ automation surfaces — the portal accelerator, ALZ-Bicep,
caf-enterprise-scale, the AVMavm-ptn-alzpattern, and the neweralzTerraform provider + ALZ library — and pick the one that fits. - Separate bootstrap (build the factory once) from platform (run it continuously), and wire OIDC so pipelines hold no stored secrets.
- Stand up subscription vending so app teams self-serve a governed subscription in minutes via a small PR.
- Reason about push (pipeline) vs pull (DINE policy) deployment, drift detection, and continuous compliance as two halves of one reconciliation loop.
- Design a platform-vs-application pipeline separation with least-privilege, per-layer deployment identities and what-if / PSRule gates.
Where this fits
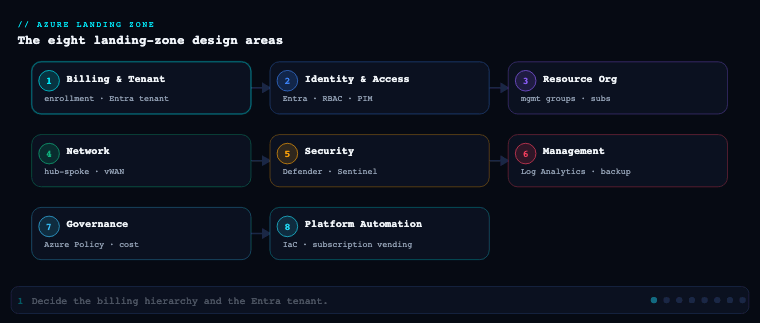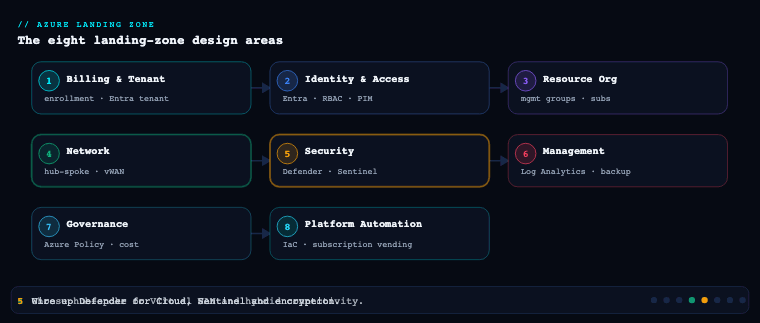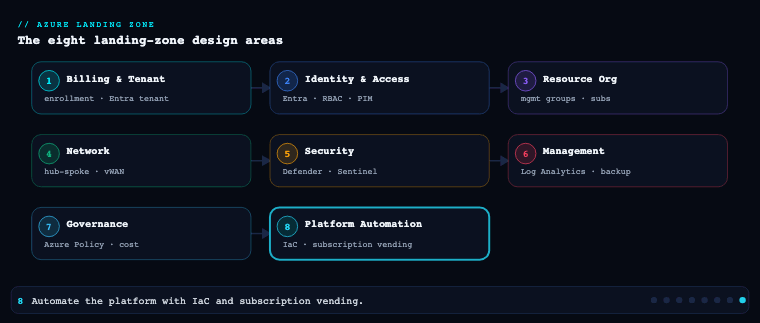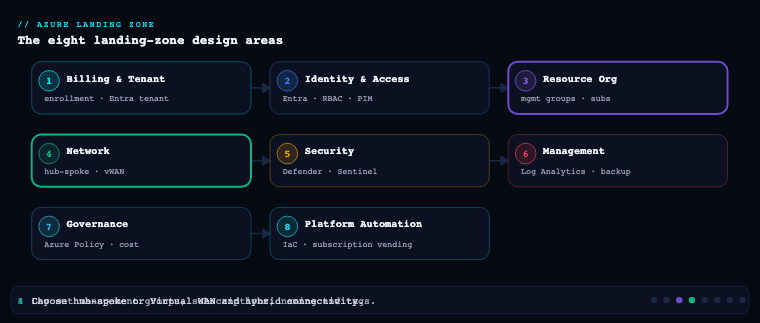
Platform Automation & DevOps is the eighth and final design area of the Azure Landing Zone (ALZ) conceptual architecture, and it is the one that makes the other seven durable. Identity, Network Topology, Resource Organization, Security, Management, Governance and the Billing/Entra-tenant decisions all describe a desired state; Platform Automation & DevOps decides how that state is expressed as code, reviewed, tested, deployed, and continuously reconciled so it never drifts. Concretely, this design area answers: in what language is the platform defined (Bicep, Terraform, or both)? Which accelerator bootstraps the management-group tree, policies and platform subscriptions? How does an application team get a governed subscription on demand (subscription vending)? What CI/CD deploys changes to the platform itself, with what gates and what identity? And what operating model does the platform team run so that “the landing zone” is a product with versioned releases rather than a one-off click-ops build that decays the day after go-live? Skip this design area and you have a beautiful architecture that is true exactly once; do it well and every other design area becomes a pull request.
Infrastructure as Code with Bicep and Terraform
What it is
Infrastructure as Code (IaC) is the practice of declaring your Azure resources — management groups, policy assignments, subscriptions, hub networks, Log Analytics workspaces, the lot — in version-controlled, machine-readable definitions that a deployment engine reconciles against the live tenant. For Azure landing zones there are two first-class, Microsoft-supported choices, and the ALZ ships both as maintained reference implementations:
- Bicep — a domain-specific language that transpiles to Azure Resource Manager (ARM) JSON. It is Azure-native, has no external state store (ARM is the state, recorded as deployment objects at the relevant scope), and is deployed by ARM directly. The ALZ ships ALZ-Bicep modules.
- Terraform — HashiCorp’s cloud-agnostic IaC tool driving the AzureRM and AzAPI providers, with an explicit, external state file as the source of truth for what it manages. The ALZ ships the Azure Verified Modules for Platform Landing Zone (ALZ) —
Azure/avm-ptn-alzand the olderAzure/caf-enterprise-scale(“CAF Enterprise-scale”) module.
Why it matters
The landing zone is governance infrastructure: a Deny policy at the intermediate-root management group affects every subscription in the tenant. You cannot afford for that to be a hand-edited portal setting that one admin remembers. IaC gives you review (PR + approvals), audit (git history of who changed which guardrail and why), repeatability (rebuild the platform in a DR tenant or a second geo), testability (validate and what-if before apply), and drift detection (the live tenant is continuously compared to the declared state). It is also the only sane way to operate at scale: hundreds of policy assignments, dozens of subscriptions and spoke networks are not maintainable by clicking.
Bicep vs Terraform for the platform — the real decision
This is the single most consequential decision in this design area. The honest answer: both are fully supported and both deploy the same ALZ reference architecture; choose on team skills and existing estate, not on a feature scoreboard.
| Dimension | Bicep | Terraform |
|---|---|---|
| Vendor / support | Microsoft-native, ships with Azure CLI; ARM is the engine | HashiCorp + Microsoft-published modules; AzureRM/AzAPI providers |
| State management | No external state — ARM stores deployments at the scope; nothing to secure/lock yourself | Explicit state file you must host (Azure Storage backend) and lock (blob lease) |
| Multi-cloud | Azure only | Cloud-agnostic — preferred if you also run AWS/GCP with one toolchain |
| Day-0 coverage of new Azure features | Often same-day (ARM-native) | Lags until the AzureRM provider adds it; AzAPI provider closes the gap |
| Preview before apply | az deployment ... what-if |
terraform plan (clearer diff, the gold standard) |
| Drift handling | What-if on redeploy; ARM deployments are idempotent | plan shows drift; can import existing resources |
| Modularity | Modules + template specs; registry via ACR or Bicep public registry | Modules + a rich public/private registry; Azure Verified Modules (AVM) |
| ALZ reference impl | ALZ-Bicep | Azure/avm-ptn-alz, caf-enterprise-scale |
| Best fit | Azure-only shop, .NET/Microsoft-aligned team, wants zero state ops | Multi-cloud, existing Terraform skills, wants explicit plan/state |
Pragmatic guidance I give clients: pick one as the platform’s primary language and standardize. Mixing Bicep and Terraform across the same layer multiplies the skills you must hire for and the failure modes you must debug. A common, legitimate split is Terraform for the platform landing zone (because the org already runs Terraform for everything) while application teams use whatever they like inside their own subscription — the guardrails are enforced by Policy, not by mandating the app team’s IaC tool.
How to do it well
- Adopt Azure Verified Modules (AVM). AVM is Microsoft’s program of pre-built, well-architected, tested Bicep and Terraform modules with consistent interfaces, telemetry, and a published contract. Building landing-zone components from AVM modules instead of raw resources gives you battle-tested defaults and a clear upgrade path. The ALZ platform pattern itself is an AVM pattern module (
avm-ptn-alz). - Separate
config(data) fromcode(logic). The ALZ accelerators are explicitly designed so your inputs — management-group names, policy parameters, regions, hub address spaces — live in declarative config files (.tfvars, Bicep.bicepparam, or library JSON/YAML), and the module logic is consumed unchanged from upstream. This lets yougit pullupstream improvements without re-merging your customizations. - Pin and version every module. Reference upstream modules by immutable version tag (a Terraform
version = "x.y.z", a Bicep registry tag, or a git SHA), neverlatest/main. Upgrades are then a deliberate, reviewed PR with awhat-if/plan, not a surprise on the next run. - Remote, locked, encrypted state (Terraform). Host state in an Azure Storage account with versioning, soft-delete, RBAC + Microsoft Entra auth (not account keys), blob-lease locking, and ideally a customer-managed key. Put the state account in the Management platform subscription, locked with
CanNotDelete. (Bicep sidesteps all of this — there is no state file to lose.) - Run
what-if/planon every PR and require it as a gate. A platform change that can’t show a clean, expected diff doesn’t merge. - Decompose by lifecycle, not by one giant root module. Keep the management-group + policy layer, the connectivity hub layer, and subscription vending in separate state/deployment units so a hub change can’t accidentally re-plan the whole tenant.
Concrete artifacts, decisions, and tools
- Artifacts: the platform IaC repository (modules + environment config); a Terraform backend definition (storage account, container, key) or the Bicep deployment-stack/scope strategy; a module version-pinning manifest; a
what-if/planartifact attached to every PR; a module-source decision record (AVM vs custom). - Decisions: Bicep vs Terraform as the primary platform language; AVM adoption; state hosting and locking (if Terraform); module versioning policy; how config is separated from code; what is deployed at MG scope vs subscription scope vs resource-group scope.
- Tools/services: Bicep + Azure Resource Manager (with
what-if, deployment stacks, template specs); Terraform with the AzureRM and AzAPI providers and an Azure Storage backend; Azure Verified Modules; ALZ-Bicep andAzure/avm-ptn-alz/Azure/caf-enterprise-scale; theAzure/namingmodule for deterministic names.
The landing-zone accelerator
What it is
The Azure landing zone accelerator is Microsoft’s opinionated, ready-to-deploy implementation of the entire ALZ conceptual architecture — the management-group hierarchy, the platform subscriptions (Management, Connectivity, Identity), the Azure Policy initiatives and assignments, RBAC, the Log Analytics workspace, hub networking, and Defender for Cloud — bootstrapped from a single configurable starting point. It comes in three flavours that all converge on the same reference design:
- Portal accelerator — a guided Azure portal experience (“Deploy Azure landing zones”) that asks for your inputs and provisions the platform. Excellent for a first deployment and for understanding the shape; less ideal as the long-term operating model because it is not, by itself, a CI/CD pipeline.
- Bicep accelerator (ALZ-Bicep) — modular Bicep that you run from a pipeline.
- Terraform accelerator (
Azure/alzaccelerator +avm-ptn-alz) — a bootstrap that scaffolds both the platform IaC and the CI/CD plumbing (repos, pipelines, identity, state backend) for you.
Why it matters
The accelerator is the difference between spending months hand-assembling a CAF-compliant platform and standing up a known-good, Microsoft-maintained baseline in days — one that already encodes the design decisions of the other seven design areas (the canonical MG tree, the ALZ custom policy set, the hub-spoke topology). Just as importantly, it gives you a supported upgrade path: as Microsoft improves the reference (new policies, new well-architected defaults), you consume those as versioned module updates rather than re-architecting. It is the fastest correct start and the thing that keeps your platform aligned with CAF over time.
Bootstrap vs platform — the key mental model
The Terraform accelerator draws a deliberate line you should preserve:
| Phase | What it creates | Run how often |
|---|---|---|
| Bootstrap | The DevOps scaffolding: the git repos, the CI/CD pipelines/workflows, the deployment identity (a Microsoft Entra app/managed identity with federated credentials / OIDC), the Terraform state storage account, and the agent/runner config | Once, to set up the factory |
| Platform (continuous) | The actual landing zone — MGs, policies, platform subs, hub network, Log Analytics — deployed by the pipelines the bootstrap created | Every change, forever, via PRs |
Internalising this prevents the classic mistake of treating the accelerator as a one-shot installer. The accelerator’s real value is that the platform phase is now a CI/CD loop you own.
How to do it well
- Start from the accelerator; don’t fork-and-forget. Take the upstream modules, drive them with your config, and stay on the upstream release train. Resist copy-pasting the module internals into your repo (you lose upgrades and inherit maintenance).
- Choose your starter config deliberately. The accelerators ship multiple starter configurations (e.g. minimal “management groups + policy only”, “complete” with connectivity, hub-and-spoke vNet vs Virtual WAN). Pick the one matching your Network Topology design-area decision so the hub the accelerator builds is the hub you actually want.
- Let the bootstrap create OIDC identity, not secrets. The Terraform accelerator can wire workload-identity federation between your pipeline and Entra so deployments use short-lived OIDC tokens with no stored client secret. Take it.
- Treat the accelerator output as your baseline, then layer org specifics. Org-specific policy exemptions, extra MGs (e.g. geo tiers for data residency), and custom initiatives go in your config layer on top of the accelerator’s defaults.
- Re-run idempotently in lower environments first. Stand the platform up in a canary/management-test scope (or a separate tenant) and prove the
plan/what-ifis clean before touching production management groups.
Concrete artifacts, decisions, and tools
- Artifacts: the chosen starter configuration; the bootstrapped repos + pipelines + state backend + deployment identity; your org-specific config overlay (MG names, policy params, hub address space, regions); an accelerator version/upgrade log.
- Decisions: portal vs Bicep vs Terraform accelerator; which starter config (hub-spoke vs Virtual WAN; minimal vs complete); GitHub vs Azure DevOps as the bootstrap target; how org customizations layer onto upstream defaults.
- Tools/services: the Azure landing zone portal accelerator; ALZ-Bicep; the
Azure/alzTerraform accelerator +avm-ptn-alz; Microsoft Entra workload identity federation (OIDC); GitHub or Azure DevOps for the bootstrapped repos and pipelines; Azure Policy built-in + ALZ custom initiatives baked into the accelerator.
Subscription vending
What it is
Subscription vending is the automated, self-service flow by which an application team receives a fully governed, network-connected, policy-compliant application landing zone subscription on demand — without a central team hand-building it. It is the productized answer to “how do app teams get into the platform,” and it is the practical embodiment of the ALZ principle of democratization (subscriptions are a unit of scale you mint freely, inside guardrails, rather than a precious thing gated by tickets). The reference implementation is the Azure/lz-vending Terraform module (with Bicep equivalents); it is the natural companion to the platform accelerator.
Why it matters
The subscription is Azure’s primary boundary for scale (quotas/limits), cost, RBAC/policy inheritance, and blast radius. If creating one is a manual, multi-week ticket, you get two failure modes: cloud velocity dies, and teams route around you (shadow IT, everything crammed into one mega-subscription that hits limits and muddies cost). Vending fixes both: app teams move at their own pace, and the platform team governs by policy-as-code applied at birth — the subscription is compliant the instant it exists because it lands under a governed management group with the right policies inherited. It is also where the platform’s self-service contract lives.
What a vending request actually does
A good vending pipeline turns a small metadata request into a complete, compliant subscription. The steps the lz-vending module orchestrates:
| Step | What happens | Why |
|---|---|---|
| Create / reference subscription | Mint a new subscription under the right billing scope (EA enrollment account or MCA invoice section), or alias an existing one | Correct cost lineage from day one |
| Management-group placement | Place it in the correct MG (e.g. Corp / Online) |
Inherits the right guardrails immediately |
| RBAC assignment | Grant the app team Owner/Contributor scoped to their subscription only | Self-service without platform access |
| Networking | Create a spoke vNet and peer it to the regional hub (or connect to Virtual WAN); register Private DNS | Connected and resolvable, hub-routed |
| Budget + tags + alerts | Apply a Cost Management budget with action-group alerts and mandatory tags (cost center, owner, env, classification) | Cost control and showback at birth |
| Resource providers + baseline | Register required resource providers; seed baseline RGs/Key Vault/identities | Ready to deploy into |
How to do it well
- Make the request a PR with a tiny schema. App teams submit a small YAML/
.tfvars(app name, cost center, environment, criticality, region/residency, budget, required connectivity) as a pull request to alanding-zonesrepo. PR review is the approval gate; merge triggers the vend. This gives you audit, review, and rollback for free. - No standing platform access for app teams. The vending pipeline runs under the platform deployment identity; it grants the app team rights scoped to their own subscription. Any elevated platform access stays behind Microsoft Entra PIM (just-in-time, approved, time-boxed).
- Govern at birth via the default management group + placement. Set the tenant’s default management group to a locked-down quarantine MG so any subscription created outside vending is non-compliant-by-default until reviewed; vending places subs explicitly so they inherit guardrails on creation.
- Standardize the baseline, parameterize the variance. Everything every subscription needs (spoke peering, DNS, budget, tags, diagnostic settings to the central Log Analytics workspace) is fixed in the module; only a handful of inputs vary per request.
- Decompose state per subscription. Each vended subscription ideally gets its own Terraform state (or a clearly partitioned slice) so one app’s changes never re-plan another’s.
Concrete artifacts, decisions, and tools
- Artifacts: the vending module + pipeline; the request intake schema (the per-subscription YAML/
.tfvarscontract); an RBAC delegation model; the per-sub budget/action-group definitions; the spoke-network and Private DNS wiring template; a subscription register (what was vended, for whom, under which MG and billing scope). - Decisions: per-workload vs per-environment subscription granularity; which billing scope subscriptions are minted under (EA enrollment account vs MCA invoice section vs CSP); default budget thresholds and alert recipients; whether app owners get Owner (with policy guardrails) or a constrained custom role; hub-peering vs Virtual WAN connection.
- Tools/services:
Azure/lz-vending(Terraform) / Bicep equivalent; Microsoft Cost Management + Billing (EA/MCA APIs to create subscriptions programmatically and set budgets); Azure Policy + default management group (governance at birth); Microsoft Entra PIM for platform elevation; Azure Private DNS and vNet peering / Virtual WAN for connectivity.
CI/CD for the platform
What it is
Platform CI/CD is the pipeline that takes a change to the landing zone itself — a new policy assignment, an MG tweak, a hub-network change, a new vended subscription — from a pull request through validation, preview, approval, and deployment, with the right identity, gates, and environment promotion. It is distinct from application CI/CD (which deploys app code into a landing zone). Here the “artifact” being deployed is governance and platform infrastructure, and the blast radius is potentially tenant-wide, so the controls are correspondingly stricter.
Why it matters
Because a single merged PR can change a Deny policy across every subscription, the platform pipeline is the control plane for your control plane. Done well it gives you peer-reviewed, auditable, gated, repeatable changes with a clear preview of impact and the ability to promote the same change through canary → production. Done badly (or not at all) you are back to admins clicking in the portal with no review, no preview, and no record — exactly the state IaC exists to eliminate.
The platform pipeline stages
A reference platform pipeline (whether GitHub Actions or Azure DevOps Pipelines) runs roughly:
| Stage | What runs | Gate |
|---|---|---|
| Validate / lint | terraform validate / bicep build, fmt/format checks, tflint, naming linter (Azure/naming) |
Block on failure |
| Static / policy test | Checkov/tfsec/PSRule for Azure (well-architected + ALZ rules), secret scanning | Block on findings |
| Plan / what-if | terraform plan / az deployment ... what-if, output attached to the PR |
Human review of the diff |
| PR approval | Required reviewers (CODEOWNERS), branch protection | Approvals + green checks |
| Apply to canary | Deploy to a non-prod MG/management-test scope or canary tenant | Automated post-deploy checks |
| Apply to production | Deploy to the real MG hierarchy / platform subs | Environment protection / manual approval |
| Post-deploy verify | Azure Resource Graph compliance queries, policy-compliance check | Alert on drift |
How to do it well
- OIDC / workload identity federation, never stored secrets. The pipeline authenticates to Azure with a Microsoft Entra app or managed identity using federated credentials — short-lived tokens, no client secret in the CI system. This is the single biggest security win and the accelerator wires it for you.
- Least-privilege, scoped deployment identities. Don’t give one god-identity Owner on the tenant root. Use separate identities per layer (one for MG/policy, one for connectivity, one for vending), each scoped to the smallest MG/subscription it needs, ideally with deployment-time elevation via PIM-for-groups.
- Branch protection + CODEOWNERS + environments. Protect
main; require PR review and passingplan/what-if; use GitHub Environments / Azure DevOps environment approvals so production apply needs an explicit human gate. - Promote the same artifact through stages. Run the identical config against a canary scope (a management-test MG branch or a second tenant) before production. Never let “tested in dev” mean “different code than prod.”
- Make
plan/what-ifa required, readable PR comment. Reviewers approve a diff, not a hope. Attach the plan output to the PR automatically. - Detect drift on a schedule. A nightly
plan/what-if(or Azure Policy compliance scan + Resource Graph query) flags anything that changed out-of-band, closing the loop between declared and live state.
Concrete artifacts, decisions, and tools
- Artifacts: the pipeline/workflow definitions (one per platform layer); the federated-credential configuration; branch-protection + CODEOWNERS rules; environment-approval definitions; the
plan/what-ifPR-comment automation; static-analysis (PSRule/Checkov) gate config; a drift-detection scheduled job. - Decisions: GitHub Actions vs Azure DevOps Pipelines; OIDC federation vs (rejected) stored secrets; how many deployment identities and at what scopes; canary/promotion topology (multi-MG vs multi-tenant); which static-analysis gates are blocking vs advisory; self-hosted vs Microsoft-hosted runners/agents (self-hosted if deploying into private-network platform resources).
- Tools/services: GitHub Actions or Azure DevOps Pipelines; Microsoft Entra workload identity federation; PSRule for Azure / Checkov / tfsec; Azure Policy compliance + Azure Resource Graph for post-deploy verification; Microsoft Entra PIM for deployment-identity elevation; GitHub Environments / Azure DevOps Environments & approvals for gating.
GitOps and the platform team operating model
What it is
GitOps is the operating discipline where git is the single source of truth for desired state, all changes flow through pull requests, and an automated system continuously reconciles the live environment to what git says — with drift detected and (optionally) auto-corrected. The platform team operating model is the human side: a dedicated platform engineering team (often the Cloud Center of Excellence / CCoE) that builds and operates “the landing zone” as an internal product — versioned, documented, supported, with application teams as its customers. Together they turn the platform from a project into a product with a release cadence.
Why it matters
Two failure modes kill landing zones over time: drift (someone clicks a change in the portal and the declared state silently diverges) and ownership rot (the original build team disbands and no one owns the platform’s evolution). GitOps attacks drift by making git authoritative and reconciliation continuous. The platform-team operating model attacks ownership rot by making the landing zone someone’s product with a backlog, releases, and SLOs. The combination is what lets a 50-team enterprise keep a single coherent, compliant platform years after go-live — and it shifts the platform team from gatekeepers (manually approving every request) to enablers (publishing self-service capabilities behind guardrails).
The operating model — platform team vs application teams
| Concern | Platform team (CCoE) owns | Application team owns |
|---|---|---|
| Management-group hierarchy & policy | ✔ (as code, via the platform repo) | — |
| Connectivity hub, firewall, DNS | ✔ | Spoke usage within guardrails |
| Subscription vending capability | ✔ (builds the vending product) | Requests a subscription via PR |
| Guardrails (Azure Policy) | ✔ (authors/assigns) | Operates inside them |
| Their application + its resources | — | ✔ (deploys into their own sub) |
| RBAC for their workload | — | ✔ (scoped to their sub) |
| Golden modules / paved road | ✔ (publishes AVM-based modules) | ✔ (consumes them) |
The principle: the platform team delegates with guardrails, not gatekeeps. App teams get Owner on their own subscription and a paved road of approved, reusable modules; the platform team ensures the guardrails they cannot remove are correct.
How to do it well
- Everything through PRs — no portal changes to the platform. Make manual changes to platform MGs/policies an exception requiring a follow-up PR to reconcile. Ideally lock down portal write access to platform scopes so the only path is the pipeline.
- Run the landing zone as a product. Versioned releases of the platform (semantic versioning), a public changelog, a backlog of guardrail/feature requests from app teams, documented SLOs (e.g. vending turnaround, policy-change lead time), and a support channel. The accelerator’s upstream releases feed your release train.
- Continuous reconciliation + drift detection. Schedule the platform pipeline (or a Policy compliance scan) to re-
plan/what-ifand alert on any divergence; remediate via PR. For workload clusters, real GitOps tooling — Flux (the native AKS GitOps extension) or Argo CD — reconciles Kubernetes state from git continuously; the same philosophy applies to the platform via scheduled IaC reconciliation. - Publish a paved road. Give app teams golden modules (AVM-based Bicep/Terraform for common patterns — a compliant web app, an AKS baseline, a data platform) so the easy path is also the compliant path. This is what makes guardrails feel like help, not handcuffs.
- Measure the platform like a product. Track DORA-style and platform-specific KPIs so you can prove the operating model is working (see below).
KPIs for the platform product
| KPI | What it tells you | Healthy direction |
|---|---|---|
| Subscription vending lead time | Self-service health | Minutes, not weeks |
| Policy-change lead time (PR → enforced) | Governance agility | Hours/days |
| Platform deployment frequency | How safely you can change the platform | Frequent, small PRs |
| Change failure rate / MTTR | Platform-change safety | Low / fast |
| % platform changes via git (vs portal) | GitOps adherence | ~100% |
| Policy-compliance % across the estate | Guardrails actually holding | High and rising |
| Configuration-drift incidents detected | Reconciliation working | Detected fast, trending down |
| Paved-road module adoption | Is the easy path the compliant path? | Rising |
Concrete artifacts, decisions, and tools
- Artifacts: the platform repo(s) as single source of truth; a platform product backlog, changelog, and versioned releases; documented operating-model RACI (who owns what); SLOs and a KPI dashboard; the paved-road module catalog; a drift-detection/reconciliation job; the contribution model (how app teams request guardrail changes via PR).
- Decisions: monorepo vs multi-repo for the platform; release cadence and versioning scheme; how (and whether) to auto-remediate drift vs alert-and-PR; whether to enforce Flux/Argo CD for workload clusters; the boundary of platform-team vs app-team responsibility; how the team is staffed (dedicated platform engineering vs rotation).
- Tools/services: GitHub/Azure DevOps (repos, PRs, branch protection, CODEOWNERS); Azure Policy + Azure Resource Graph (continuous compliance/drift visibility); Flux (AKS GitOps extension) / Argo CD for Kubernetes reconciliation; Azure Verified Modules for the paved road; a KPI/dashboard surface (Azure Workbooks / Power BI over Resource Graph and Cost Management).
Real-world enterprise scenario
Aranya Logistics is a fictional pan-India freight and last-mile-delivery company — ~2,300 employees, 38 application teams, a data-residency obligation (India regions only for customer data), and a board mandate to move off a chaotic single-subscription Azure estate onto a governed platform within two quarters. Their newly-formed platform engineering team (six engineers, branded internally as the CCoE) owns the Platform Automation & DevOps design area end to end.
IaC with Bicep and Terraform. Aranya already runs Terraform for their on-prem and a small AWS analytics footprint, so they standardize the platform on Terraform + Azure Verified Modules, building the landing zone from Azure/avm-ptn-alz and vending from Azure/lz-vending. Application teams are not forced onto Terraform — guardrails are enforced by Policy, so app teams use Bicep or Terraform as they prefer inside their own subscriptions. Platform state lives in an Azure Storage account in the Management subscription with versioning, soft-delete, Entra-auth (no account keys), blob-lease locking, a customer-managed key, and a CanNotDelete lock. Every upstream module is pinned to an exact version; upgrades are deliberate PRs.
The landing-zone accelerator. They bootstrap with the Azure/alz Terraform accelerator, choosing the hub-and-spoke “complete” starter (matching their Network Topology decision: Azure Firewall + ExpressRoute hub, not Virtual WAN). The bootstrap phase (run once) creates the GitHub repos, the GitHub Actions workflows, the Terraform state backend, and a Microsoft Entra app with OIDC federated credentials — no client secrets anywhere. The platform phase then runs continuously via PRs. On top of the accelerator’s defaults, Aranya layers org specifics in a config overlay: two extra geo MG tiers (Corp-IN-Central, Corp-IN-South) carrying an Allowed locations policy pinned to centralindia/southindia, plus three custom policy initiatives. They stand the whole platform up first in a management-test MG branch and prove a clean plan before touching production MGs.
Subscription vending. They productize onboarding with lz-vending. An app team opens a pull request to the landing-zones repo containing a ~15-line YAML: app name, cost center, environment, criticality, residency (IN-Central/IN-South), budget, and connectivity. PR review by the platform team is the approval gate; merge triggers a GitHub Actions workflow that mints the subscription under their MCA invoice section, places it in Corp-IN-Central or Online, peers its spoke vNet to the regional hub, registers Private DNS, grants the app team Owner scoped to that subscription only (platform elevation stays behind Entra PIM), seeds four baseline RGs (-app/-data/-net/-shared), wires diagnostic settings to the central Log Analytics workspace, and sets a ₹-denominated Cost Management budget with action-group alerts at 60/90/100%. A previously three-week, ticket-driven subscription request now completes in under 18 minutes, fully compliant.
Platform CI/CD. All platform changes run through GitHub Actions authenticating via OIDC workload identity federation (zero stored secrets). Each layer has its own scoped deployment identity (MG/policy, connectivity, vending) — no tenant-root god-identity. The pipeline lints (terraform validate, tflint, Azure/naming), runs PSRule for Azure and Checkov as blocking gates, posts the terraform plan as a PR comment for human review, requires CODEOWNERS approval and branch protection on main, applies first to the management-test canary scope with post-deploy Azure Resource Graph checks, then applies to production behind a GitHub Environment manual approval. A nightly plan flags any out-of-band drift.
GitOps and the platform team operating model. Aranya runs the landing zone as an internal product: semantically versioned releases, a changelog, a backlog fed by app-team guardrail requests (submitted as PRs/issues), and published SLOs (vending < 30 min; policy-change lead time < 2 days). No portal changes to platform scopes are permitted — portal write access to platform MGs is locked down, so the pipeline is the only path; the nightly reconciliation alerts on drift and the team remediates via PR. They publish a paved road of AVM-based golden modules (a compliant App Service web app, an AKS baseline using the Flux AKS GitOps extension for workload reconciliation, and a data-platform module) so the easy path is the compliant path. A Power-BI-over-Resource-Graph KPI dashboard tracks vending lead time, policy-compliance %, % of changes via git, and drift incidents.
Measurable outcome after two quarters: 41 application landing zones vended (target 35); ~99% reduction in subscription provisioning lead time (3 weeks → 18 min); 100% of platform changes via git (portal writes to platform scopes disabled); 0 stored deployment secrets (all OIDC); policy-compliance across the new estate at 98% (live via Resource Graph); zero residency violations (the Allowed locations policy pinned at the geo MG tier is inherited everywhere beneath); and paved-road module adoption at 73% of new workloads — the landing zone now evolves through reviewed pull requests rather than tribal knowledge.
Going deeper
The core sections above give you the operating model. This section is for the platform engineer who has to build the machine and defend its edges: what the ALZ automation surfaces actually are under the branding, how the two deployment engines (pipeline push and policy pull) divide the work, how drift and compliance close into one loop, and where scale, cost, identity and API-version reality bite.
The ALZ automation surfaces, decoded
“The accelerator” is an umbrella over several distinct, independently-versioned artifacts. Knowing which is which stops you mixing incompatible pieces:
| Surface | What it actually is | When it’s the right pick |
|---|---|---|
| Portal accelerator (“Deploy Azure landing zones”) | A guided portal experience that deploys the enterprise-scale ARM reference at management-group scope | A first, click-through baseline to see the shape; not a long-term CI/CD model |
ALZ-Bicep (Azure/ALZ-Bicep) |
Hand-composable Bicep modules for each ALZ layer, run from your own pipeline | Azure-only shops standardizing on Bicep who want module-level control |
caf-enterprise-scale (Azure/caf-enterprise-scale) |
The original monolithic Terraform module — the whole ALZ in one big module driven by archetype JSON | Existing deployments; new ones are steered toward AVM |
avm-ptn-alz (Azure/avm-ptn-alz) |
The Azure Verified Module pattern for the ALZ — smaller, composable, AVM-contracted | The current Microsoft-recommended Terraform path for new builds |
The alz provider + ALZ library |
A Terraform provider (Azure/alz) whose data sources read the Azure Landing Zones Library (archetypes, policy definitions/assignments as versioned JSON) and hand the composed data to the module |
The “config-as-data” engine under avm-ptn-alz; lets you pin/override the reference architecture as data |
Azure/alz accelerator (the ALZ PowerShell module, Deploy-Accelerator) |
The bootstrap tool that scaffolds repos, pipelines, deployment identity + OIDC, and state — then wires in avm-ptn-alz |
Standing up the whole factory (bootstrap and platform) in one guided run |
The mental shift the newer stack introduces is the ALZ library as versioned data. Older caf-enterprise-scale baked archetypes into module inputs; the alz provider externalises the entire reference (which policies exist, which assignments land at which archetype) into a library you reference by release tag and override surgically. Upgrading the platform’s guardrails becomes “bump the library version, read the plan” rather than “re-merge a fork.” Bicep’s equivalent lever is AVM modules pinned by registry tag plus deployment stacks for lifecycle; there is no external library to compose, because ARM itself is the engine.
Two deployment engines: pipeline push vs policy pull
A subtle but load-bearing point most teams miss: the ALZ deploys itself through two different engines, and they are complementary, not competing.
- Pipeline push (imperative-ish, on change). Your CI/CD runs
terraform apply/az deployment mg createand pushes the declared resources — MGs, assignments, the hub vNet, Log Analytics — into existence. It runs when a PR merges. This is the structure. - Policy pull (reconciling, continuous). Many ALZ guardrails are
DeployIfNotExists(DINE) andModifypolicies. Once assigned (by the pipeline), the Azure Policy engine — not your pipeline — evaluates every in-scope resource and, via the assignment’s managed identity, remediates it: deploys the missing diagnostic setting, enables Defender for Cloud on a new subscription, adds the required tag. This is a pull/reconcile loop that fires on resource create/update and via remediation tasks, with no pipeline run at all.
Why it matters: the pipeline can’t be everywhere every second, but the policy engine can. ALZ deliberately uses push for the scaffolding and pull (DINE) for the per-resource hygiene that must hold across thousands of resources created by app teams the platform pipeline never sees. Getting this division right is the difference between a platform that scales and one where the pipeline is a bottleneck.
Two consequences to internalise:
- DINE assignments need an identity with the right role at the right scope, granted at assignment time. A DINE policy that can’t act (missing role) leaves compliant-looking resources that were never actually remediated — a classic silent failure. The ALZ modules wire these role assignments for you; if you author custom DINE policies, you own that wiring.
- New DINE/Modify policies don’t retroactively fix existing resources until a remediation task runs. Assigning a “deploy diagnostics” policy today makes new resources compliant on creation but leaves yesterday’s resources non-compliant until you remediate them. Bake remediation into the platform pipeline or a scheduled job.
Drift detection and continuous compliance — one loop
“Drift” hides in two places, and you need both halves of the loop:
- IaC drift — the declared state (git) vs what the deployment engine last applied vs the live tenant. A scheduled
terraform plan/what-if(nightly is common) surfaces resources changed out-of-band. Terraform detects it against state; note that a resource deleted in the portal reappears on the next apply, but a resource added out-of-band is invisible to Terraform unless it isimported or a policy denies it. Bicep/ARM has no state file, so deployment stacks (GA) fill the gap: a stack tracks its managed resources, can deny changes to them, and can delete resources removed from the template — the closest Bicep gets to Terraform-style lifecycle management. - Policy / compliance drift — the live estate vs the guardrails. Azure Policy compliance state plus Azure Resource Graph queries tell you what is actually non-compliant right now, across every subscription, without a pipeline run. This is your continuous compliance signal.
The mature pattern runs both: nightly IaC plan/what-if for platform-structure drift, and continuous Policy + Resource Graph for estate-wide compliance — the first guards the factory, the second guards everything the factory stamped. Remediate structure via PR; remediate policy findings via remediation task (for DINE/Modify) or PR/exception (for genuine Deny gaps).
The testing pyramid for platform IaC
You don’t “test” a landing zone by deploying it and eyeballing the portal. There is a real pyramid, cheapest first:
| Layer | Tools | Catches |
|---|---|---|
| Format + lint | terraform fmt, bicep build/lint, tflint, Azure/naming |
Syntax, style, bad names, obvious misconfiguration |
| Static / policy-as-code | PSRule for Azure, Checkov, tfsec, secret scanning | Well-architected + ALZ rule violations before any deploy |
| Unit / contract | Pester (Bicep/PowerShell), Terratest / native terraform test |
A module behaves to its contract on a mock/ephemeral scope |
| Preview | terraform plan, az deployment ... what-if attached to the PR |
The actual diff a human approves |
| Post-deploy verify | Azure Resource Graph queries, Policy compliance scan | Reality matches intent after apply |
Two honest caveats. what-if is not omniscient: some resource providers report noisy or incomplete diffs (properties they can’t evaluate show as “no change” or “ignore”), so treat it as high-signal-but-not-proof and layer post-deploy verification. And plan is only as truthful as the state and provider: a provider bug or an out-of-band change it can’t see will make plan lie — which is exactly why continuous compliance (policy-side) backstops it.
Platform vs application pipelines — the hard separation
The most common architectural smell is one mega-pipeline that deploys the platform and the apps. Keep them separate, with separate identities:
- Platform pipeline(s) deploy governance and shared infrastructure (MGs, policy, hub, DNS, vending). Blast radius: tenant-wide. They run under per-layer, least-privilege deployment identities (one for MG/policy, one for connectivity, one for vending) — never a single Owner-on-tenant-root god identity. Elevation is time-boxed via Entra PIM (for groups).
- Application pipelines deploy workloads into an already-vended subscription, under an identity scoped to that subscription only. They cannot touch platform scopes — Policy enforces the guardrails they can’t remove.
Decompose the platform itself by lifecycle, not one giant root module: the MG/policy layer, the connectivity layer, and each vended subscription get their own state / deployment unit, so a hub change can’t re-plan the entire tenant and one app’s vend never re-plans another’s. At scale this also dodges two real limits: ARM write-request throttling (a monolith touching thousands of resources hits rate limits and slow what-ifs) and Terraform plan time (a single caf-enterprise-scale state covering the whole estate becomes a multi-minute plan and a coarse blast radius).
Scale, cost, identity and version reality
- Management-group depth is capped at six levels beneath the (invisible) tenant root, above the subscription level. Design the tree within that; don’t encode every org nuance as another MG tier — use policy parameters and tags for variance.
- Azure Policy has per-scope caps on assignments and definitions (in the low hundreds). Consolidate related policies into initiatives (policy sets) rather than assigning dozens individually; assign initiatives high in the tree and let inheritance do the work.
- Subscription creation needs billing-scope rights, not just tenant RBAC. Programmatic vending requires the right role on the billing object — e.g. an MCA invoice section (the “Azure subscription creator” role), an EA enrollment/account owner, or an MPA for partners — which is a different permission plane from the management-group RBAC that governs the subscription afterward. Wire the deployment identity into both.
- Terraform
azurermv4 is a hard version gate for 2025-era builds: it madesubscription_idon the provider mandatory, removed long-deprecated fields, and reshaped some resources — pin the provider (~> 4.x) and read the upgrade guide before bumping. Theazapiprovider remains the escape hatch for Azure features the typedazurermprovider hasn’t surfaced yet (often same-day for new services). - State is a secret. A Terraform state file can contain generated passwords, keys and connection strings in plaintext. Host it in an Azure Storage account with Entra auth (no account keys), versioning, soft-delete, blob-lease locking, a customer-managed key, and a
CanNotDeletelock — in the Management platform subscription, reachable only by the deployment identities. Bicep sidesteps this (no state), but its parameter files and pipeline logs can still leak secrets — reference Key Vault, don’t inline. - The machinery has a small but real cost: the state storage account, a Log Analytics workspace, the self-hosted runners/agents (needed when you deploy into private-network platform resources), and Defender for Cloud plans. Budget it as platform overhead, not per-app cost — and remember that a self-hosted runner inside a private VNet is usually the reason behind a “why can’t the pipeline reach the resource?” ticket.
Practice challenges
Work these in order — they escalate from reading the reference to designing the machine. Each has a worked solution; try it before you open it. (These are design/authoring exercises; nothing here claims to have been run against a live tenant, and every identifier is a placeholder.)
1 (Beginner) — Pick the primary language. Your org runs Terraform for on-prem and a little AWS, has no Bicep skills, and wants one toolchain. Which primary platform IaC language, and what is the one-line justification?
<details> <summary>Show solution</summary>
Terraform, standardized as the platform’s primary language. Justification: existing Terraform skills plus a multi-cloud toolchain outweigh Bicep’s day-0 Azure coverage, and app teams can still use Bicep inside their own subscriptions because guardrails are enforced by Policy, not by mandating their IaC tool.
Why: the decision is driven by team skills and estate, not a feature scoreboard — both tools deploy the same ALZ reference architecture. </details>
2 (Beginner) — Separate bootstrap from platform. Sort these into the bootstrap phase vs the platform phase: the Terraform state storage account; a Deny policy assignment at the intermediate-root MG; the GitHub Actions workflows; the hub vNet; the Entra app with OIDC federated credentials; a vended app subscription.
<details> <summary>Show solution</summary>
Bootstrap (build the factory once): state storage account, GitHub Actions workflows, Entra app + OIDC federated credentials.
Platform (run continuously via PRs): the Deny policy assignment, the hub vNet, the vended app subscription.
Why: bootstrap creates the DevOps scaffolding and identity; everything the pipelines then deploy — governance, network, subscriptions — is the platform phase, forever. </details>
3 (Intermediate) — Classify push vs pull. For each guardrail, say whether ALZ typically deploys it by pipeline push or policy pull (DINE/Modify): (a) the management-group tree; (b) “diagnostic settings must ship logs to the central Log Analytics workspace” on every new resource; © the connectivity hub firewall; (d) “enable Defender for Cloud on every subscription”; (e) a required-tags default value.
<details> <summary>Show solution</summary>
Push (pipeline): (a) MG tree, © hub firewall — structural, deployed on change.
Pull (DINE/Modify policy): (b) diagnostic settings (DeployIfNotExists), (d) Defender for Cloud enablement (DeployIfNotExists), (e) required-tags default (Modify).
Why: structure is stamped by the pipeline on merge; per-resource hygiene that must hold across everything app teams create is reconciled continuously by the Policy engine’s managed identity — the pipeline never sees those resources. </details>
4 (Intermediate) — Design the vending request. Write the ~12-line YAML contract an app team submits (as a PR) to vend a subscription. Include only inputs that legitimately vary per request; everything standard is fixed in the module.
<details> <summary>Show solution</summary>
# landing-zones/requests/payments-prod.yaml  (representative)
appName: payments
environment: prod            # dev | test | prod
costCenter: "CC-PLACEHOLDER"
owner: "team-payments@PLACEHOLDER"
criticality: high            # low | medium | high
residency: IN-Central        # drives MG placement + Allowed-locations
managementGroup: Corp-IN-Central
budgetMonthly: 250000        # INR; action-group alerts at 60/90/100%
connectivity: hub-peer       # hub-peer | vwan | isolated
requirePrivateDns: true
billingScope: mca-invoice-PLACEHOLDER
Why: the app team supplies intent (who, where, how much, how connected); the module fixes the invariants (spoke peering pattern, DNS wiring, diagnostic settings, RBAC scoping, tag schema) so every subscription is compliant-by-construction and only a handful of inputs vary. </details>
5 (Advanced) — Harden the deployment identity. A junior engineer proposes one Entra app with Owner at the tenant root and a client secret stored in GitHub Actions secrets, “so the pipeline can do anything.” Give three concrete changes that fix the security posture, each with the mechanism.
<details> <summary>Show solution</summary>
- Replace the stored secret with OIDC. Configure workload identity federation — a federated credential with a subject such as
repo:ORG/REPO:environment:prod— so the pipeline gets a short-lived token and no secret is stored anywhere. - Drop tenant-root Owner; use per-layer least-privilege identities. One identity for MG/policy, one for connectivity, one for vending, each scoped to the smallest MG/subscription it needs — no single god-identity blast radius.
- Gate elevation with Entra PIM (for groups). Any standing high privilege becomes just-in-time, approved, and time-boxed, with an audit trail.
Why: the three failure modes here are a leakable long-lived credential, a tenant-wide blast radius, and standing privilege — OIDC, scoped identities, and PIM neutralise them respectively. </details>
6 (Advanced) — Close the drift loop. A Deny policy shows as assigned in git, but resources that violate it still exist in one subscription, and last night’s terraform plan was clean. Explain how both can be true, then describe the two-part detection you would add.
<details> <summary>Show solution</summary>
How both are true: Terraform’s plan compares its declared platform resources against state — the policy assignment exists and matches, so plan is clean. But Deny only blocks new or updated non-compliant resources; pre-existing violating resources are unaffected, and they live in an app subscription the platform pipeline doesn’t manage, so they are invisible to that plan.
Detection to add: (1) continuous compliance — an Azure Policy compliance scan plus an Azure Resource Graph query across the estate that reports the actual non-compliant resources, independent of any pipeline; (2) for effects that can remediate (DeployIfNotExists/Modify), a scheduled remediation task to clear the backlog. Genuine Deny violations that predate the assignment surface as findings to fix by PR or exception.
Why: the IaC plan guards the factory’s structure; Policy + Resource Graph guard everything the factory stamped — you need both halves of the loop.
</details>
Common beginner mistakes
These are conceptual traps — the wrong mental model a newcomer brings — as opposed to the operational pitfalls listed further down. Fixing the model fixes a whole class of errors.
“IaC means I write it once and I’m done.” The misconception: infrastructure as code is a build step, like compiling. The reality: the platform is a living declaration that is continuously reconciled. The value isn’t the first apply; it’s the 500th — every drift caught, every guardrail re-asserted, every upgrade a reviewed diff. If you treat it as a one-time install, you’ll skip drift detection and the continuous-compliance loop, which is exactly where landing zones rot. Right model: the code is the source of truth forever, and a scheduled plan/what-if plus a Policy scan is how it stays true.
“The portal accelerator is the automation.” The misconception: clicking “Deploy Azure landing zones” in the portal means you have platform automation. The reality: the portal accelerator is a great way to see the shape and get a baseline, but on its own it is a one-shot deployment with no repo, no pipeline, no OIDC, and no upgrade path. Right model: automation is the bootstrap → platform loop (repos, pipelines, identity, state) that deploys and re-deploys from code; the portal is a starting point you graduate off of.
“Terraform state is just a cache I can delete.” The misconception: state is a throwaway file. The reality: state is Terraform’s source of truth for what it manages and often contains secrets in plaintext; lose it and Terraform will try to recreate everything, leak it and you’ve leaked keys. Right model: state is a secured, versioned, locked, encrypted asset in the Management subscription — treat it like a production database, not a temp file. (Bicep has no state, but its parameter files and logs can still leak — reference Key Vault, don’t inline.)
“A policy assignment fixes the resources that already exist.” The misconception: assign a DeployIfNotExists policy and yesterday’s resources become compliant. The reality: DINE/Modify policies act on create/update and only fix the backlog when a remediation task runs; Deny never touches what already exists at all. Right model: assigning a guardrail governs the future; fixing the past needs an explicit remediation task (for DINE/Modify) or a PR/exception (for Deny violations that predate it).
“A clean what-if/plan means my change is safe.” The misconception: if the preview shows the diff I expected, deployment is guaranteed correct. The reality: what-if can report noisy or incomplete diffs for some resource types, and plan is only as truthful as the state and provider — an out-of-band change Terraform can’t see, or a provider quirk, makes the preview lie. Right model: the preview is high-signal, not proof; back it with static analysis before (PSRule/Checkov) and post-deploy verification after (Resource Graph + Policy compliance).
“Subscription vending is just a script that creates a subscription.” The misconception: vending equals calling the create-subscription API. The reality: creating the subscription is the smallest part; vending also places it under the right management group (so guardrails inherit immediately), peers its spoke to the hub, wires Private DNS, applies budget/tags/diagnostics, and grants the app team RBAC scoped to that subscription only — all as one governed, PR-reviewed transaction. Right model: vending is a compliance-at-birth product, not an API call; the subscription is correct the instant it exists.
“Guardrails are handcuffs that slow app teams down.” The misconception: governance and self-service are in tension. The reality: done right, the platform team delegates with guardrails — app teams get Owner on their own subscription and a paved road of approved modules, and vending hands them a governed subscription in minutes. Right model: the compliant path is the easy path; the guardrails you can’t remove are the price of self-service you didn’t have to wait three weeks for.
Deliverables & checklist
Common pitfalls
- Treating the accelerator as a one-shot installer. Running the portal accelerator once and walking away leaves you with a platform that immediately starts drifting and has no upgrade path. Keep the bootstrap-vs-platform distinction: the accelerator builds the factory; the platform must then be a continuous CI/CD loop you own, consuming upstream releases as versioned updates.
- Mixing Bicep and Terraform in the same layer without a reason. Each tool multiplies the skills you must hire for and the failure modes you must debug. Standardize one primary language for the platform; if app teams want a different tool inside their own subscription, that’s fine — guardrails are enforced by Policy, not by mandating their IaC tool.
- Storing pipeline secrets instead of using OIDC. A long-lived client secret in your CI system is a tenant-wide credential waiting to leak. Use Microsoft Entra workload identity federation (OIDC) so deployments use short-lived tokens with no stored secret — the accelerator wires this for you.
- One god deployment identity with Owner on the tenant root. A single over-privileged identity is a catastrophic blast radius and a compliance red flag. Use least-privilege, per-layer deployment identities scoped to the smallest MG/subscription each needs, with elevation via PIM where required.
- Manual portal changes to the platform (drift). The moment someone clicks a policy or MG change in the portal, git is no longer the truth and your reconciliation lies. Enforce GitOps — disable portal write access to platform scopes, route every change through a PR, and run scheduled drift detection to catch exceptions.
- Centralized, ticket-driven subscription creation. Hand-building subscriptions kills velocity and breeds shadow IT. Productize vending (
Azure/lz-vending) so app teams self-serve via a small PR and receive a governed, connected, budgeted subscription in minutes — with no standing platform access. - Building the platform but never running it as a product. Without an owning platform team, a backlog, versioned releases and SLOs, the landing zone decays into tribal knowledge the day the build team disbands. Run it as an internal product with a clear operating model and a paved road, measured by platform KPIs.
Glossary
- Infrastructure as Code (IaC) — declaring Azure resources in version-controlled, machine-readable files that a deployment engine reconciles against the live tenant, instead of clicking in the portal.
- Bicep — Azure’s native IaC language; transpiles to ARM JSON and is deployed by ARM with no external state file.
- ARM (Azure Resource Manager) — the Azure control-plane API and deployment engine that creates/updates/governs resources; it stores Bicep/ARM deployments at the target scope.
- Terraform — HashiCorp’s cloud-agnostic IaC tool; uses providers (AzureRM, AzAPI, alz) and an explicit state file as its source of truth.
- AzureRM provider — Terraform’s primary, typed Azure provider. v4 made
subscription_idmandatory and removed deprecated fields — a version gate to plan for. - AzAPI provider — a thin Terraform provider that speaks raw ARM, used to reach Azure features the typed AzureRM provider hasn’t surfaced yet (often same-day for new services).
- State file — Terraform’s record of what it manages; can hold secrets in plaintext, so it must be secured, versioned, locked and encrypted.
- Azure Verified Modules (AVM) — Microsoft’s program of pre-built, tested, contracted Bicep/Terraform modules with consistent interfaces; the recommended building blocks for landing zones and the paved road.
avm-ptn-alz— the AVM pattern module for the Azure Landing Zone; the current recommended Terraform path for new ALZ builds.caf-enterprise-scale— the original monolithic Terraform module for the ALZ (the whole platform in one module driven by archetype JSON); still supported, but new builds are steered to AVM.- ALZ-Bicep — Microsoft’s modular Bicep implementation of the ALZ, run from your own pipeline.
alzprovider + ALZ library — a Terraform provider whose data sources read the Azure Landing Zones Library (archetypes and policies as versioned JSON), externalising the reference architecture as data you pin and override.- Accelerator — Microsoft’s ready-to-deploy ALZ implementation. Comes as a portal experience, ALZ-Bicep, or the
Azure/alzTerraform accelerator (theALZPowerShell module’sDeploy-Accelerator). - Bootstrap phase — the one-time setup that creates the DevOps scaffolding: repos, pipelines, deployment identity + OIDC, and Terraform state.
- Platform phase — the continuous deployment of the actual landing zone (MGs, policy, hub, vending) by the pipelines the bootstrap created.
- Subscription vending — the automated, self-service flow that gives an app team a fully governed, connected, budgeted subscription on demand via a small PR; reference modules
Azure/lz-vending(Terraform) andavm-ptn-lz-sub-vending(Bicep AVM pattern). - Management group (MG) — a container above subscriptions for applying policy and RBAC by inheritance; the tree is capped at six levels beneath the tenant root.
- Azure Policy — the guardrail engine; rules evaluated against resources with effects such as
Audit,Deny,DeployIfNotExistsandModify. - DeployIfNotExists (DINE) — a policy effect that deploys a missing resource (e.g. a diagnostic setting) via the assignment’s managed identity — a continuous pull/reconcile engine, distinct from a pipeline push.
- Modify — a policy effect that adds or updates properties/tags on resources (also via a managed identity).
- Remediation task — the job that applies a DINE/
Modifypolicy to pre-existing non-compliant resources (new resources are handled on create/update). - Deployment stack — a Bicep/ARM feature that manages a set of resources as one unit with deny-settings and cleanup of removed resources — the closest Bicep gets to Terraform-style lifecycle/drift management.
- What-if / plan — the preview of changes before apply (
az deployment ... what-if/terraform plan); a required, human-reviewed PR gate — high-signal, not absolute proof. - Drift — divergence between declared state (git), applied state, and the live tenant; detected by scheduled
plan/what-ifand by Policy + Resource Graph. - Azure Resource Graph — a fast, tenant-wide query service over Azure resources and Policy compliance; the backbone of continuous-compliance and drift dashboards.
- OIDC / workload identity federation — lets a pipeline authenticate to Microsoft Entra with a short-lived token and no stored secret, via a federated credential keyed to the repo/branch/environment.
- Microsoft Entra PIM — Privileged Identity Management; just-in-time, approved, time-boxed elevation for high-privilege access (e.g. platform deployment identities).
- CODEOWNERS / branch protection / environments — the git controls that require reviewers, passing checks, and manual approval gates before a platform change reaches production.
- PSRule for Azure — policy-as-code static analysis that checks IaC against well-architected and ALZ rules before deployment.
- Paved road — a catalog of approved, reusable (AVM-based) modules that makes the compliant path the easy path for app teams.
- GitOps — the discipline where git is the single source of truth, all changes flow through PRs, and an automated system continuously reconciles the live environment to git.
- CCoE (Cloud Center of Excellence) — the platform-engineering team that builds and operates the landing zone as an internal product.
- Billing scope — the commerce object a subscription is created under (EA enrollment account, MCA invoice section, or MPA/partner); programmatic vending needs rights here, separate from MG RBAC.
What’s next
This installment closes the eight Azure Landing Zone Design Areas — from here, the next part of the series steps back to the operating cadence that keeps the whole platform healthy: landing-zone lifecycle management and continuous compliance, turning the design areas you’ve now built into an ongoing, measurable practice.